Crawlable Pages: How to Check Crawlability and Crawl Accessibility
A page that works in Chrome can still be invisible to a crawler. Check the status code, robots.txt, rendered HTML, internal links, and sitemap entry in order.
On this page
A page can work perfectly in Chrome and still be invisible to a search crawler. A deployment can return a login wall, a blocked route, or a client-rendered shell while your team sees a complete page. Check the repository files and HTTP response together. That is where most crawlability failures become obvious.
Quick Answer: A page is crawlable when a search engine can request its URL, receive a meaningful response, and discover it through permitted links or sitemaps. Check the status code, robots.txt, robots directives, canonical URL, rendered HTML, internal links, and sitemap entry before you investigate rankings.
What does crawlable mean in SEO?
A crawlable page accepts a crawler's request and returns content the crawler can process. Google describes three basic conditions for eligibility: Googlebot can access the page, the page returns a successful HTTP response, and the page contains indexable content. See Google's technical requirements for the source documentation.
Crawling, indexing, and ranking happen at different stages. Crawling means fetching a URL. Indexing means deciding whether the fetched content belongs in a search index. Ranking means ordering eligible pages for a query. A crawlable page can remain unindexed because it has duplicate content, weak signals, a noindex directive, or a search engine's own quality decisions.
Crawlability describes whether a crawler can reach and fetch a page. Crawl accessibility covers the technical conditions around that request, including DNS, TLS, authentication, robots.txt, response codes, redirects, content type, and server availability. A public page with a 200 response can still have poor crawl accessibility if its only discovery path requires a button click handled by JavaScript.
For example, a documentation route at /docs/webhooks might load for a human after a React application runs. If the server sends only an empty app shell and the route appears nowhere in an HTML anchor, a crawler has less reliable evidence that the page exists. Google can process JavaScript, but it first needs to fetch the page and later render it. A server-rendered title, text, and link remove an avoidable dependency. Google documents this crawl, render, and index sequence in its JavaScript SEO guidance.
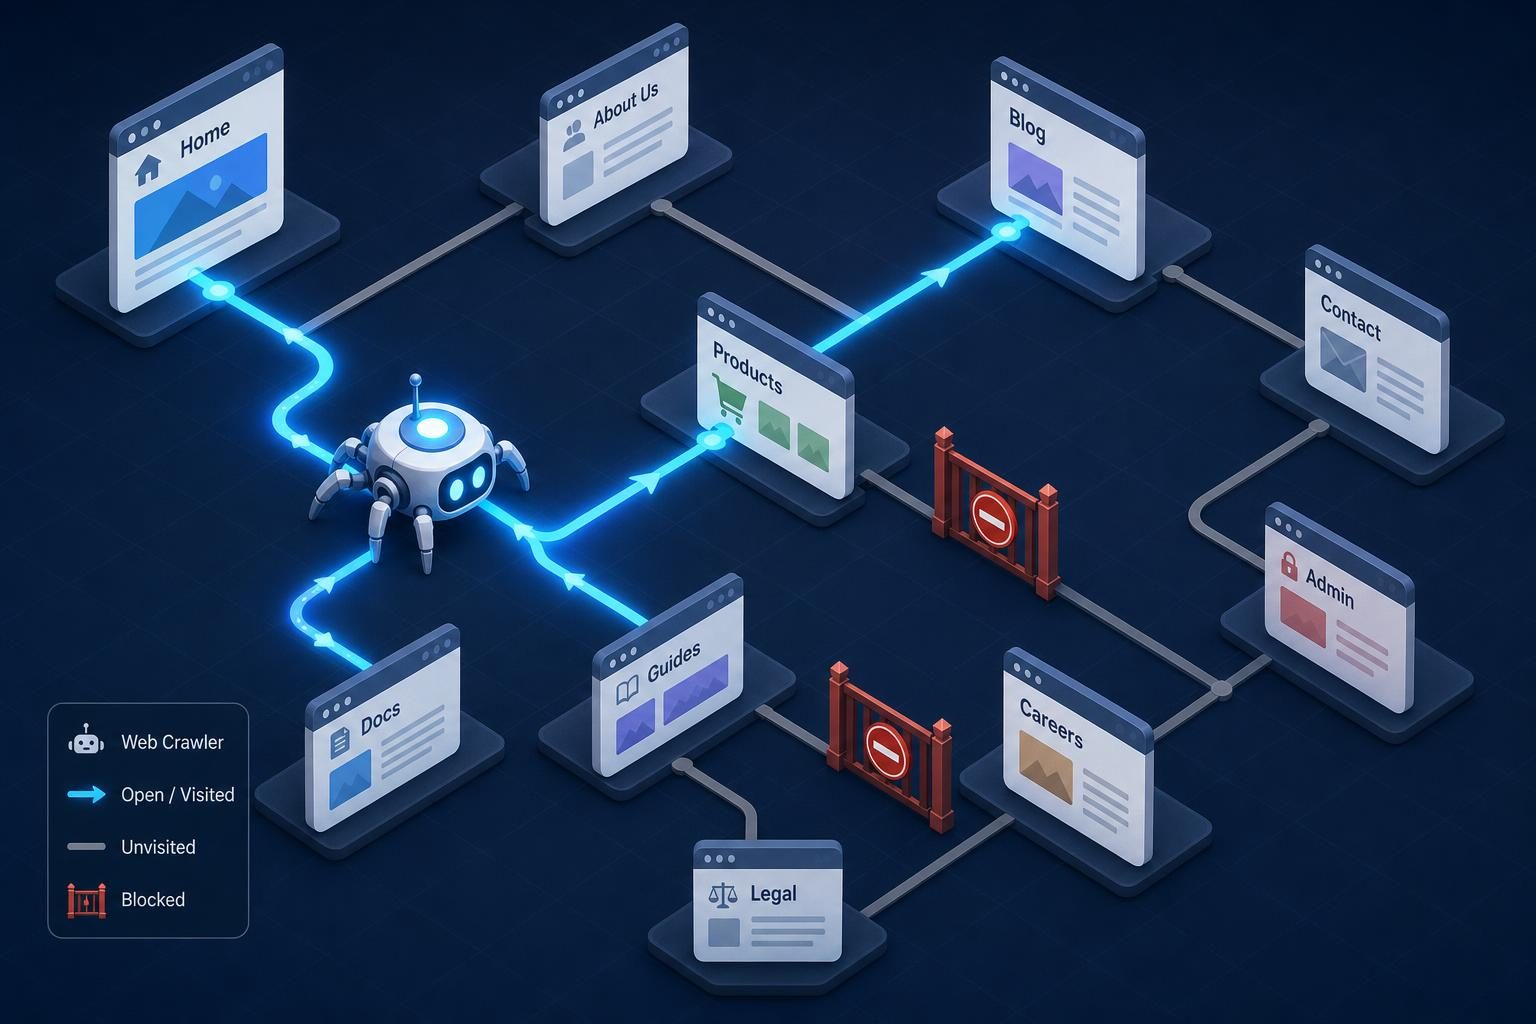
A crawlable URL must be fetchable, permitted, meaningful, and discoverable before indexing decisions can happen.
What prevents a page from being crawlable?
Most failures leave evidence in a repository file or an HTTP response. Start there instead of guessing from a search result.
- robots.txt blocks the route. A rule such as
Disallow: /docs/tells compliant crawlers not to request URLs under that path. A blocked URL cannot be reliably evaluated for its page content. - noindex blocks indexing. A
noindexvalue in a meta robots tag orX-Robots-Tagresponse header tells a crawler not to place the page in its index. Robots.txt and noindex do different jobs. If robots.txt blocks the URL, the crawler might not fetch the response containing noindex. - The response fails. A 404 or 410 says the resource is gone. A 5xx response signals a server problem. A long redirect chain wastes requests, while a redirect to an unrelated page can make the original route function as a soft 404.
- The page returns the wrong content. A route that returns a 200 status with a generic “page not found” template is a soft 404. A staging authentication wall can return 200 and still prevent public crawl accessibility.
- The canonical points elsewhere. A canonical tag such as
<link rel="canonical" href="https://example.com/docs">tells search engines which URL represents the content. A typo, staging hostname, or unrelated canonical creates conflicting signals.
User-agent: *
Disallow: /admin/
Disallow: /private/
Allow: /docs/
Sitemap: https://example.com/sitemap.xml
In this example, public documentation remains permitted, while administrative routes stay blocked. Check whether generated robots.txt matches the routes that production actually serves. The Robots Exclusion Protocol specification documents the standard behind robots.txt rules.
Robots.txt controls crawling access; noindex controls indexing after a crawler can read the response.
How to check crawlability step by step
Run the checks in the same order a crawler encounters the site. Local repository checks catch regressions before deployment, while Search Console shows Google's observed state after deployment.
- Inspect the HTTP response. Request a representative URL and record the final status, redirect chain, content type, and response headers. An intended landing page should normally return 200 with HTML. Check whether authentication, a WAF, or a server error changes the result for an unauthenticated request.
- Read the rendered HTML. Check the title, main text, canonical tag, robots meta tag, hreflang links where relevant, and links to related routes. Inspect the rendered DOM as well as the initial response. Content that exists only after a failed client-side request is not dependable crawl input.
- Open robots.txt and the sitemap. Test the exact path against every relevant rule. Then inspect the XML sitemap for the canonical, public URL. Remove deleted routes and URLs that redirect, return errors, or carry noindex.
- Trace internal links. Find a path from a navigation page, index page, or related document. Use ordinary anchors with an
href, such as<a href="/docs/webhooks">Webhooks</a>. Google says it generally parses anchor elements with href attributes more reliably than script-only navigation; see its link best practices. - Test JavaScript routes. Disable JavaScript in a browser, inspect server-rendered output, and compare it with the rendered page. Verify that route data loads without a private API, cookie, or client-side error. A visible page is not proof that a crawler received the same content.
- Compare Search Console data. Use URL Inspection for a specific deployed URL, then review Page Indexing and Crawl Stats reports for patterns. Treat those reports as production evidence, not a substitute for checking the code that caused the response.
| Artifact | Pass condition | Typical failure |
|---|---|---|
| HTTP response | 200 HTML for a public page | 5xx, login wall, redirect chain |
| Rendered HTML | Content and links appear | Empty app shell |
| robots.txt | Target path is permitted | Broad Disallow rule |
| Sitemap | Canonical public URLs only | 404 or redirected entries |
How to make a website more crawlable
Fix the route and the discovery path together. A successful response without an internal link can remain difficult to find; a perfect link to a blocked route still fails.
- Link important pages with HTML anchors. When you add
/docs/webhooks, link it from the documentation index and a related guide. Do not make the only route a click handler on adiv. SEOAgent's automated internal linking feature can inspect internal link relationships and suggest links for review. - Keep the XML sitemap accurate. Include canonical, public URLs that return 200. Remove deleted documentation pages instead of leaving them in the sitemap. A sitemap helps discovery; it does not override robots.txt, noindex, or a failing response.
- Review robots.txt after route changes. A broad rule such as
Disallow: /can enter a production build through an environment variable or generated template. Keep private admin paths blocked, but permit public product, documentation, and article paths. - Return the right status code. Use 404 or 410 for removed content with no replacement. Use a permanent redirect only when a replacement page serves the same user need. Avoid redirecting every deleted route to the homepage.
- Reduce duplicate paths. Choose one trailing-slash policy, one hostname, and one canonical URL format. Redirect alternate versions in one hop where possible, then keep only the final URLs in internal links and sitemaps.
Use the topic cluster workflow when a documentation set has related pages but weak paths between them. The goal is a readable link graph in the repository, not a promise of rankings or traffic.
Auditing crawlability in a coding-agent workflow
SEOAgent fits sites whose source lives in Git and whose developers work through Claude Code, Cursor, Codex, or another coding agent. It runs through the user's own model inside that coding agent, examines the repository, and proposes edits to files in the repo. The user approves each change.
That workflow matters for crawlability because the evidence usually sits in files such as public/robots.txt, sitemap generators, route definitions, metadata components, templates, and Markdown content. A dashboard can report that a URL is blocked. A repository audit can point to the rule or component that produced the block.
- Run the SEOAgent Skill or the local
seoagentCLI from the repository. Use the documented invocation for your installation; no command syntax is assumed here. - Review the audit's files and URLs. Confirm that a suggested change addresses a real route, rather than weakening a deliberate private-area rule.
- Approve only the edits you want the coding agent to write. Inspect the diff for robots.txt, canonical tags, sitemap generation, metadata, and links.
- Run the local checks again after staging the changes. Then deploy through your existing process and validate representative production URLs with HTTP inspection and Search Console.
SEOAgent does not publish to a CMS, deploy your application, or replace your release process. The coding agent writes approved changes into your repo, and your team ships them. Cloud Search Console analysis, keyword research, competitor research, and evidence-backed suggestions are available in the paid tier; the local repository workflow remains the useful starting point for file-level crawl checks.
Approval-gated repository edits keep crawl fixes reviewable as ordinary code changes instead of opaque dashboard actions.
Crawlability checklist for a production release
Paste this checklist into a pull request for every new route, migration, or framework change.
- Important public URLs return 200 and the expected HTML content.
- Redirects finish at the intended canonical URL without unnecessary hops.
- robots.txt permits public routes and blocks only deliberate private areas.
- No accidental
noindexmeta tag orX-Robots-Tagremains. - Canonical tags use the production hostname and match sitemap URLs.
- Sitemap entries return 200 and exclude deleted, redirected, and private URLs.
- Important pages have ordinary HTML links from relevant index or navigation pages.
- JavaScript rendering does not supply the only copy of the page's main content.
- The deployed output matches the approved repository diff.
Use this symptom table during review.
| Symptom | Likely cause | First check |
|---|---|---|
| Page missing from discovery | Weak internal linking or sitemap omission | HTML anchors and XML sitemap |
| Crawler blocked | robots.txt or authentication rules | Production robots.txt and response |
| Page excluded after fetch | noindex, duplicate content, or canonical mismatch | Rendered meta tags and canonical |
| URL marked as error | 404, 5xx, soft 404, or redirect problem | Final HTTP response and page body |
Do not apply this advice to private account pages, admin tools, checkout sessions, or content intentionally excluded from search. Those routes may need authentication or noindex by design. Crawlability is a release requirement for public pages, not a reason to expose private data.
For a repository-based site, start with the route, response, and link graph. SEOAgent can inspect those files through your coding agent and propose approval-gated changes before you ship the next build.
References
Put SEO on autopilot in your own editor
SEOAgent runs as a free skill inside Claude Code, Cursor, and Codex — on the model you already pay for. Audit, plan, and write SEO content right in your repo, with every change reviewed before it ships. No second AI subscription.
Your first SEO pull request in about 5 minutes. You pick the repo, and you merge every change.
What do you use to work on your site?
Pick one above and we take you to the right setup.